I have a Python script that launches a URL that is a downloadable file. Is there some way to have Python display the download progress as oppose to launching the browser?
81
votes
12 Answers
117
votes
I've just written a super simple (slightly hacky) approach to this for scraping PDFs off a certain site. Note, it only works correctly on Unix based systems (Linux, mac os) as PowerShell does not handle "\r":
import sys
import requests

link = "http://indy/abcde1245"
file_name = "download.data"
with open(file_name, "wb") as f:
    print("Downloading %s" % file_name)
    response = requests.get(link, stream=True)
    total_length = response.headers.get('content-length')

    if total_length is None: # no content length header
        f.write(response.content)
    else:
        dl = 0
        total_length = int(total_length)
        for data in response.iter_content(chunk_size=4096):
            dl += len(data)
            f.write(data)
            done = int(50 * dl / total_length)
            sys.stdout.write("\r[%s%s]" % ('=' * done, ' ' * (50-done)) )
            sys.stdout.flush()
It uses the requests library so you'll need to install that. This outputs something like the following into your console:
>Downloading download.data
>[============= ]
The progress bar is 52 characters wide in the script (2 characters are simply the [] so 50 characters of progress). Each = represents 2% of the download.
75
votes
You can use the 'clint' package (written by the same author as 'requests') to add a simple progress bar to your downloads like this:
from clint.textui import progress

r = requests.get(url, stream=True)
path = '/some/path/for/file.txt'
with open(path, 'wb') as f:
    total_length = int(r.headers.get('content-length'))
    for chunk in progress.bar(r.iter_content(chunk_size=1024), expected_size=(total_length/1024) + 1):
        if chunk:
            f.write(chunk)
            f.flush()
which will give you a dynamic output which will look like this:
[################################] 5210/5210 - 00:00:01
It should work on multiple platforms as well! You can also change the bar to dots or a spinner with .dots and .mill instead of .bar.
Enjoy!
35
votes
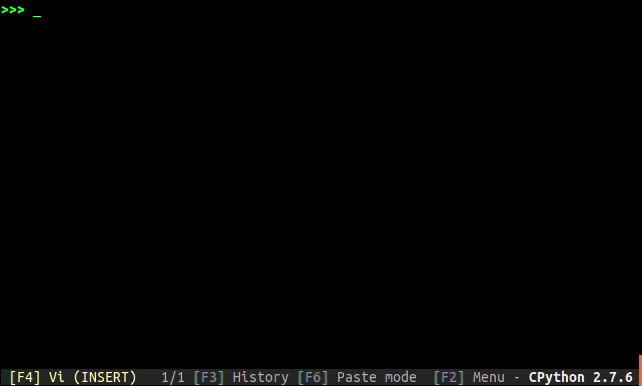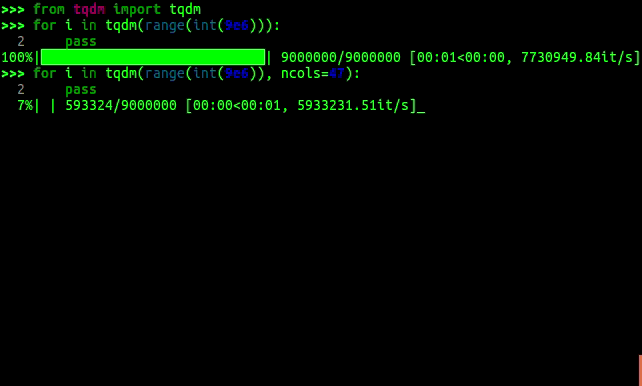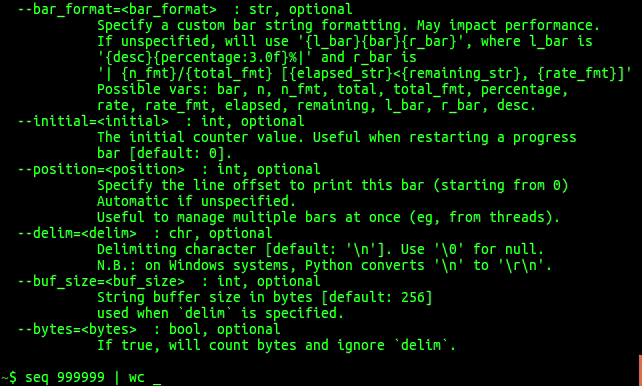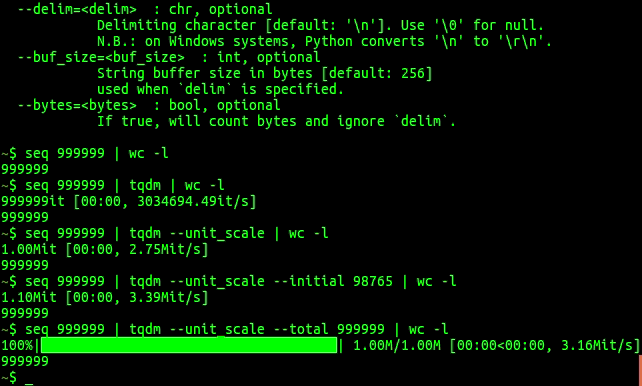
Python 3 with TQDM
This is the suggested technique from the TQDM docs.
import urllib.request

from tqdm import tqdm


class DownloadProgressBar(tqdm):
    def update_to(self, b=1, bsize=1, tsize=None):
        if tsize is not None:
            self.total = tsize
        self.update(b * bsize - self.n)


def download_url(url, output_path):
    with DownloadProgressBar(unit='B', unit_scale=True,
                             miniters=1, desc=url.split('/')[-1]) as t:
        urllib.request.urlretrieve(url, filename=output_path, reporthook=t.update_to)
15
votes
11
votes
There is an answer with requests and tqdm.
import requests
from tqdm import tqdm


def download(url: str, fname: str):
    resp = requests.get(url, stream=True)
    total = int(resp.headers.get('content-length', 0))
    with open(fname, 'wb') as file, tqdm(
        desc=fname,
        total=total,
        unit='iB',
        unit_scale=True,
        unit_divisor=1024,
    ) as bar:
        for data in resp.iter_content(chunk_size=1024):
            size = file.write(data)
            bar.update(size)
Gist: https://gist.github.com/yanqd0/c13ed29e29432e3cf3e7c38467f42f51
6
votes
You can also use click. It has a good library for progress bar:
import click

with click.progressbar(length=total_size, label='Downloading files') as bar:
    for file in files:
        download(file)
        bar.update(file.size)
5
votes
Sorry for being late with an answer; just updated the tqdm docs:
https://github.com/tqdm/tqdm/#hooks-and-callbacks
Using urllib.urlretrieve and OOP:
import urllib
from tqdm.auto import tqdm

class TqdmUpTo(tqdm):
    """Provides `update_to(n)` which uses `tqdm.update(delta_n)`."""
    def update_to(self, b=1, bsize=1, tsize=None):
        """
        b  : Blocks transferred so far
        bsize  : Size of each block
        tsize  : Total size
        """
        if tsize is not None:
            self.total = tsize
        self.update(b * bsize - self.n)  # will also set self.n = b * bsize

eg_link = "https://github.com/tqdm/tqdm/releases/download/v4.46.0/tqdm-4.46.0-py2.py3-none-any.whl"
eg_file = eg_link.split('/')[-1]
with TqdmUpTo(unit='B', unit_scale=True, unit_divisor=1024, miniters=1,
              desc=eg_file) as t:  # all optional kwargs
    urllib.urlretrieve(
        eg_link, filename=eg_file, reporthook=t.update_to, data=None)
    t.total = t.n
or using requests.get and file wrappers:
import requests
from tqdm.auto import tqdm

eg_link = "https://github.com/tqdm/tqdm/releases/download/v4.46.0/tqdm-4.46.0-py2.py3-none-any.whl"
eg_file = eg_link.split('/')[-1]
response = requests.get(eg_link, stream=True)
with tqdm.wrapattr(open(eg_file, "wb"), "write", miniters=1,
                   total=int(response.headers.get('content-length', 0)),
                   desc=eg_file) as fout:
    for chunk in response.iter_content(chunk_size=4096):
        fout.write(chunk)
You could of course mix & match techniques.
3
votes
The tqdm package now includes a function designed to handle exactly this type of situation: wrapattr. You just wrap an object's read (or write) attribute, and tqdm handles the rest. Here's a simple download function that puts it all together with requests:
def download(url, filename):
    import functools
    import pathlib
    import shutil
    import requests
    import tqdm

    r = requests.get(url, stream=True, allow_redirects=True)
    if r.status_code != 200:
        r.raise_for_status()  # Will only raise for 4xx codes, so...
        raise RuntimeError(f"Request to {url} returned status code {r.status_code}")
    file_size = int(r.headers.get('Content-Length', 0))

    path = pathlib.Path(filename).expanduser().resolve()
    path.parent.mkdir(parents=True, exist_ok=True)

    desc = "(Unknown total file size)" if file_size == 0 else ""
    r.raw.read = functools.partial(r.raw.read, decode_content=True)  # Decompress if needed
    with tqdm.tqdm.wrapattr(r.raw, "read", total=file_size, desc=desc) as r_raw:
        with path.open("wb") as f:
            shutil.copyfileobj(r_raw, f)

    return path
2
votes
Another good option is wget:
import wget
wget.download('http://download.geonames.org/export/zip/US.zip')
The output will look like this:
11% [........ ] 73728 / 633847
Source: https://medium.com/@petehouston/download-files-with-progress-in-python-96f14f6417a2
1
votes
# Define Progress Bar function
def print_progressbar(total, current, barsize=60):
    progress = int(current*barsize/total)
    completed = str(int(current*100/total)) + '%'
    print('[', chr(9608)*progress, ' ', completed, '.'*(barsize-progress), '] ', str(i)+'/'+str(total), sep='', end='\r', flush=True)
# Sample Code
total = 6000
barsize = 60
print_frequency = max(min(total//barsize, 100), 1)
print("Start Task..", flush=True)
for i in range(1, total+1):
  if i%print_frequency == 0 or i == 1:
    print_progressbar(total, i, barsize)
print("\nFinished", flush=True)
# Snapshot of Progress Bar :
Below lines are for illustrations only. In command prompt you will see single progress bar showing incremental progress.
[ 0%............................................................] 1/6000

[██████████ 16%..................................................] 1000/6000

[████████████████████ 33%........................................] 2000/6000

[██████████████████████████████ 50%..............................] 3000/6000

[████████████████████████████████████████ 66%....................] 4000/6000

[██████████████████████████████████████████████████ 83%..........] 5000/6000

[████████████████████████████████████████████████████████████ 100%] 6000/6000
0
votes
Just some improvements of @rich-jones's answer
 import re
 import request
 from clint.textui import progress

 def get_filename(cd):
    """
    Get filename from content-disposition
    """
    if not cd:
        return None
    fname = re.findall('filename=(.+)', cd)
    if len(fname) == 0:
        return None
    return fname[0].replace('"', "")

def stream_download_file(url, output, chunk_size=1024, session=None, verbose=False):

    if session:
        file = session.get(url, stream=True)
    else:
        file = requests.get(url, stream=True)

    file_name = get_filename(file.headers.get('content-disposition'))
    filepath = "{}/{}".format(output, file_name)

    if verbose:
        print ("Downloading {}".format(file_name))

    with open(filepath, 'wb') as f:
        total_length = int(file.headers.get('content-length'))
        for chunk in progress.bar(file.iter_content(chunk_size=chunk_size), expected_size=(total_length/chunk_size) + 1):
            if chunk:
                f.write(chunk)
                f.flush()
    if verbose:
        print ("Finished")
-1
votes
You can stream a downloads as it is here -> Stream a Download.
Also you can Stream Uploads.
The most important streaming a request is done unless you try to access the response.content with just 2 lines
for line in r.iter_lines():
    if line:
        print(line)
